SMBs should plan for cloud outages by deciding which systems truly need rapid recovery, then choosing the simplest failover design that meets those needs: backups for low-priority workloads, warm standby for important applications, and multi-region architectures only for systems where downtime has immediate operational or revenue impact. The most effective strategy is not “zero downtime at any cost,” but a tested recovery plan built around realistic recovery time and data loss targets.
Key takeaways
- For most SMBs, the right cloud outage strategy is not full active-active everywhere; it is a tiered design that matches recovery targets to business-critical systems.
- Recovery planning should start with RTO and RPO, because those targets determine whether backups, warm standby, or multi-region replication are appropriate.
- A second region does not guarantee continuity if identity, DNS, secrets, databases, and deployment pipelines remain single points of failure.
- Failover plans only become reliable when they are tested regularly with documented runbooks, ownership, and rollback procedures.
- Typical SMB cloud resilience projects succeed when they protect the most important workloads first instead of trying to make every application highly available on day one.
Cloud outages are normal operational risks, not rare exceptions
Even mature cloud platforms experience service interruptions. Sometimes the issue is a full regional event, but more often it is a dependency problem: identity services are slow, a managed database becomes unavailable, DNS changes do not propagate as expected, an availability zone has networking trouble, or a deployment pipeline pushes a bad release that looks like an outage to users. For SMBs, the practical lesson is simple: “in the cloud” does not automatically mean resilient.
Business leaders often assume resilience is included once an application runs on AWS, Azure, or Google Cloud. In practice, the provider secures the infrastructure, while your team is still responsible for architecture choices, backup design, configuration recovery, application behavior, and operational response. If a workload depends on one region, one database instance, one CI/CD system, and one DNS path, it can still fail hard. In our experience, outage planning gets better when companies stop asking, “Which cloud is safest?” and start asking, “What happens when one important dependency fails?”
That shift matters because not every outage deserves the same investment. Email, file storage, e-commerce checkout, internal ERP access, customer portals, and scheduled batch jobs all have different tolerance for downtime and data loss. Treating every system as equally critical usually leads to either overspending or under-protecting the applications that actually keep the business moving.
Start with business impact: define RTO, RPO, and system tiers
Before discussing regions, load balancers, or replication, define two recovery targets for each major workload. RTO, or recovery time objective, is how quickly the service must be restored. RPO, or recovery point objective, is how much data loss is acceptable, measured in time. A customer ordering system might require an RTO under one hour and an RPO near zero. An internal reporting dashboard might tolerate an RTO of a day and an RPO of several hours.
Once those targets are documented, place systems into tiers. This is where SMBs usually gain clarity fast. Tier 1 covers revenue-generating or operationally critical systems such as public websites with transactions, line-of-business apps, identity platforms, or warehouse integrations. Tier 2 includes important tools that can run in degraded mode for a while. Tier 3 includes development, analytics, archives, and non-urgent internal services. These tiers prevent the expensive mistake of building multi-region failover for everything.
A practical decision framework
- List critical services: website, APIs, file services, ERP, CRM, databases, VPN, identity, and third-party integrations.
- Assign business impact: revenue loss, operational stoppage, compliance exposure, customer experience damage, or reputational risk.
- Set RTO/RPO: use realistic targets agreed by operations and leadership, not just IT preferences.
- Map dependencies: DNS, identity provider, secrets manager, storage, queues, payment gateways, and external APIs.
- Choose a resilience pattern: backup/restore, pilot light, warm standby, active-passive, or active-active.
- Test and revise: run failover exercises and update assumptions after each change.
This is the step many organizations skip. They jump directly to tooling, then discover their real bottleneck is not compute capacity but an undocumented dependency, a manual database promotion step, or a SaaS integration that cannot fail over cleanly.
Choose the right failover model for each workload
There is no single “best” cloud failover pattern for SMBs. The right model depends on your recovery targets, application design, staffing, and budget. Four patterns cover most real-world needs. The simplest is backup and restore: data is backed up to another region or account, infrastructure is defined with tools such as Terraform or AWS CloudFormation, and the service is rebuilt after an outage. This is low cost, but recovery can take hours or longer, so it fits Tier 3 or some Tier 2 systems.
Next is the pilot light model. Core data services are replicated and minimal infrastructure exists in the secondary region, but application capacity is scaled up only during an incident. This reduces recovery time without paying full-time production cost in both regions. A step up is warm standby, where a smaller but functional version of the environment is always running in a second region. Warm standby works well for SMB customer portals, internal apps with strict uptime needs, and e-commerce platforms where prolonged downtime is expensive.
The most advanced model is active-active, with traffic distributed across regions simultaneously. This can deliver very low RTO and avoid full cutover events, but it introduces complexity around database consistency, session state, cache invalidation, observability, and release coordination. For most SMBs, active-active is appropriate only when the application is designed for it from the start or when the business impact of downtime clearly justifies the added engineering and operating cost.
Typical fit by pattern
- Backup and restore: internal tools, document archives, non-critical batch systems.
- Pilot light: business applications that can tolerate some recovery delay but need reliable data protection.
- Warm standby: customer-facing websites, ordering systems, partner portals, and selected APIs.
- Active-active: high-volume digital products where even short outages materially disrupt revenue or operations.
Typical implementation timelines vary widely, but many SMB backup/restore improvements can be completed in a few weeks, warm standby designs often take several weeks to a few months depending on application complexity, and active-active programs frequently require a longer modernization effort because the application itself must support distributed operation.
Multi-region architecture: what actually has to fail over
When people say they want “multi-region,” they often mean web servers in two places. That is not enough. Real failover includes the entire service chain: networking, DNS, identity, application runtime, configuration, data stores, file assets, background jobs, secrets, and monitoring. A web tier that survives while authentication, object storage, or the primary database remains unavailable still results in a business outage.
For stateless application components, the pattern is straightforward. Containerized apps on Kubernetes, Amazon ECS, Azure Container Apps, or virtual machine scale sets can be deployed in two regions using infrastructure as code and CI/CD pipelines. Traffic can be routed with services such as AWS Route 53, Azure Traffic Manager, Azure Front Door, Cloudflare Load Balancing, or a global application delivery platform. Health checks need to be tuned carefully so they detect a real failure without triggering unnecessary failovers during a transient blip.
Data is where architecture becomes harder. Managed relational databases may support cross-region read replicas or failover groups, but promotion steps, write lag, and application connection handling still need design work. Object storage can often replicate across regions, though versioning, retention, and recovery permissions matter. Shared file systems, message queues, and caches all have their own limits. If your application stores session state locally or assumes a single writable database endpoint, multi-region cutover will be painful until those assumptions are removed.
Components commonly overlooked
- DNS and certificates: routing, TTL settings, certificate renewal, and domain registrar access.
- Identity and access: SSO, MFA dependencies, privileged break-glass accounts, and federation settings.
- Secrets and keys: replication of secrets managers, KMS policies, and application credentials.
- CI/CD tooling: the ability to deploy during an incident if the primary pipeline or artifact registry is unavailable.
- Observability: logs, metrics, tracing, and alerting that remain accessible during a regional failure.
- Third-party services: payment processors, tax engines, shipping APIs, or SaaS connectors that may still be a single point of failure.
At BCW Technology Solutions, we often find that the fastest resilience gains come not from adding more infrastructure, but from removing these hidden single points of failure and documenting the order of operations for recovery.
Cost, complexity, and the tradeoffs SMBs should expect
Multi-region resilience is valuable, but it is not free. Costs usually rise in three categories: duplicate or partially duplicated infrastructure, data replication and storage, and engineering effort to design, test, and maintain the environment. Warm standby often increases monthly cloud spend by a noticeable but manageable amount because a smaller secondary environment runs continuously. Active-active can cost materially more because both regions are serving production traffic and the application must support that model operationally.
There are also hidden costs. More environments mean more patching, more monitoring, more release coordination, and more chances for configuration drift. Teams need clear ownership for incident response and strong change management so the secondary region does not quietly fall behind the primary. For SMBs with lean internal IT teams, a simpler and well-tested warm standby can be far more effective than an ambitious architecture that nobody has time to maintain.
A practical budgeting approach is to price resilience by workload tier rather than trying to estimate one giant business continuity number. Ask what one hour of downtime means for your ordering platform, your operations system, or your customer support queue. Then compare that impact to the recurring cost of replication, standby capacity, and test exercises. In many cases, the right answer is mixed: strong protection for one or two critical systems, basic restore capability for the rest.
Testing and operating failover plans so they work under pressure
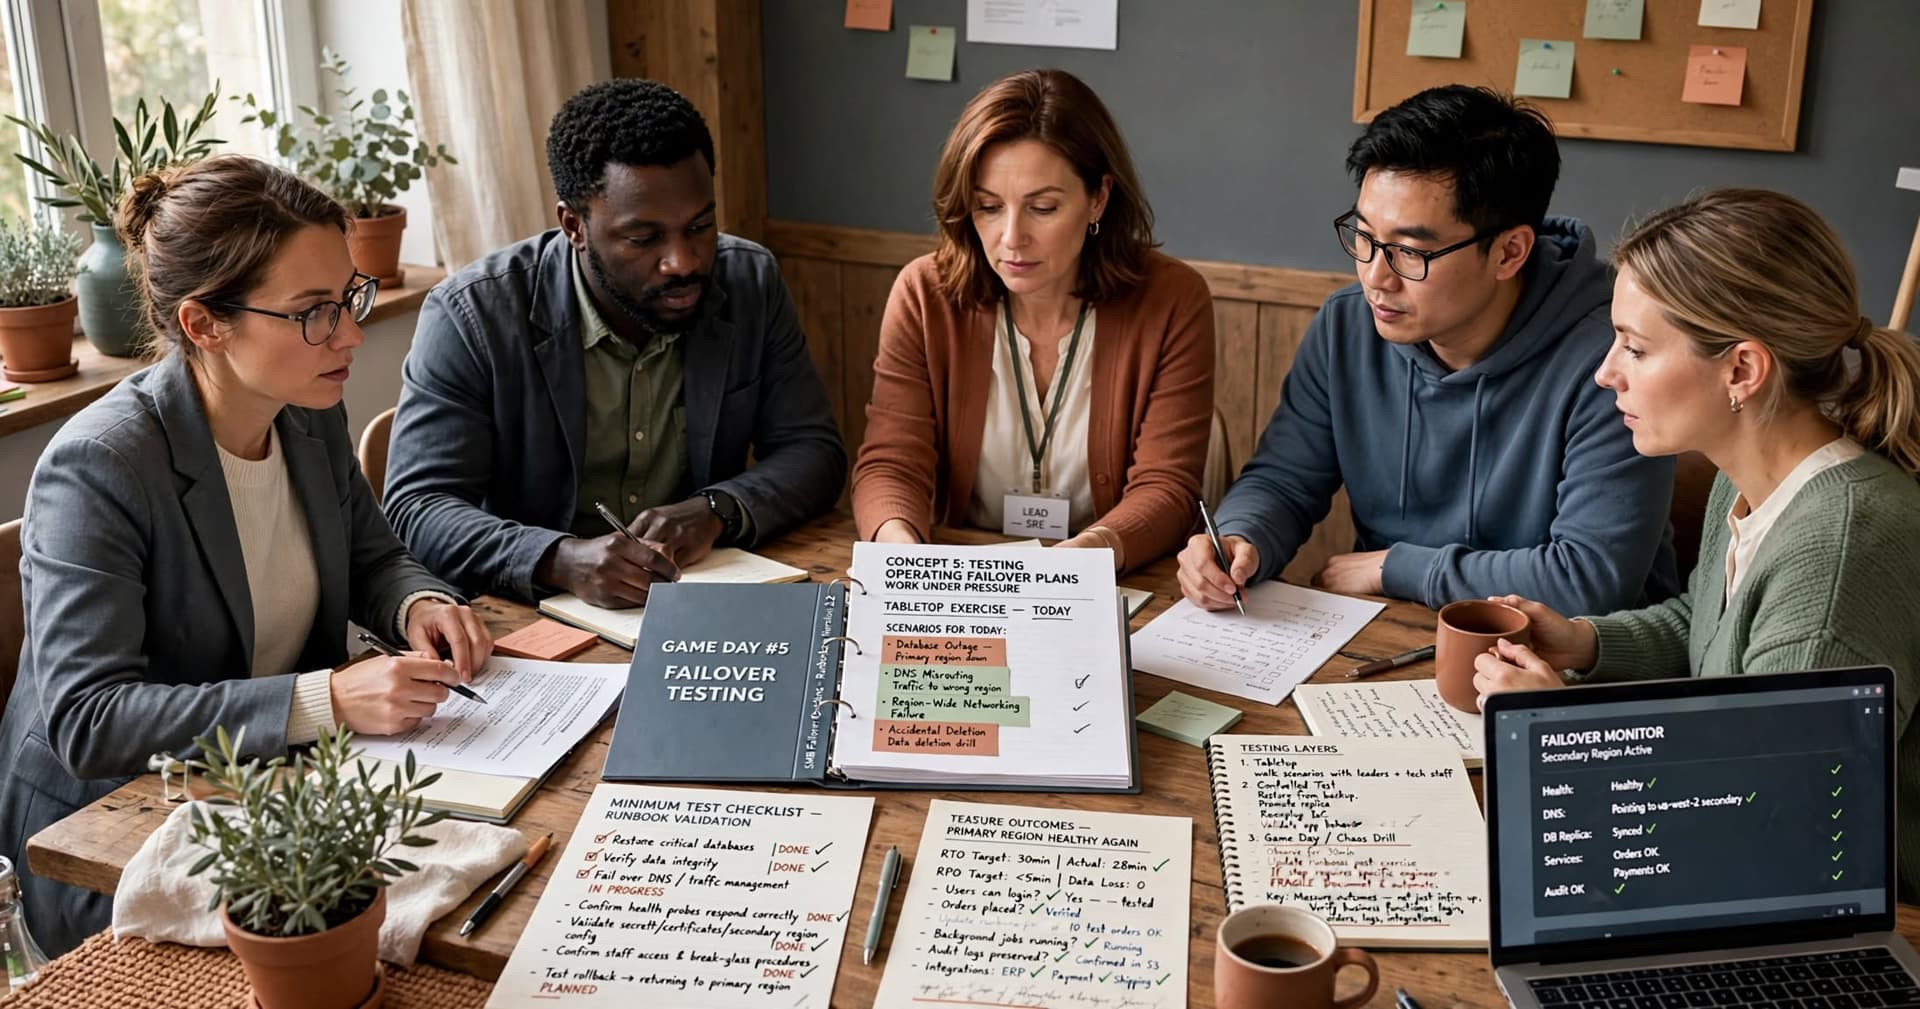
A failover design on a diagram is not a recovery capability. The only reliable proof is testing. At minimum, teams should document runbooks that define who declares an incident, who has authority to fail over, what the exact cutover steps are, how customer communication is handled internally, and how rollback works once the primary region is healthy again. If any step depends on a specific engineer remembering tribal knowledge, the plan is fragile.
Testing should happen in layers. Start with tabletop exercises, where leaders and technical staff walk through scenarios such as a database outage, region-wide networking failure, DNS misrouting, or accidental deletion. Then move to controlled technical tests: restore from backup into a clean environment, promote a replica, switch DNS, redeploy from infrastructure as code, and validate application behavior. More mature teams use game days or chaos-style drills in non-production to verify alarms, automation, and on-call response.
The best tests measure outcomes against the agreed RTO and RPO, not just whether the infrastructure came up. Can users log in? Can orders be placed? Are background jobs running? Are audit logs preserved? Are integrations with ERP, payment, or shipping systems still functioning? After each test, update runbooks, automation, and architecture. Resilience is an operating discipline, not a one-time project.
Minimum test checklist
- Restore critical databases from backup and verify data integrity.
- Fail over DNS or traffic management and confirm health probes behave correctly.
- Validate secrets, certificates, and environment configuration in the secondary region.
- Confirm staff can access consoles using least-privilege or break-glass procedures.
- Test rollback steps so returning to the primary region is predictable.
- Record actual recovery time and data loss observed during the exercise.
Common pitfalls and a practical roadmap for SMBs
The most common mistake is overbuilding too early. Companies hear “multi-region” and start duplicating infrastructure before they have clean backups, infrastructure as code, dependency maps, or tested restores. Another frequent problem is protecting the application tier while ignoring data gravity. If restoring a database, promoting a replica, or re-pointing integrations takes too long, the second region does not deliver real continuity. A third pitfall is assuming managed services fail over automatically in a way the application can tolerate.
A more reliable roadmap starts small and moves in stages. First, inventory critical workloads and set RTO/RPO targets. Second, make every environment reproducible with Terraform, CloudFormation, Bicep, or equivalent tooling. Third, harden backups with cross-region or cross-account copies, retention policies, and restore testing. Fourth, add warm standby for the one or two workloads where downtime hurts most. Fifth, automate failover steps where possible and test them regularly. Only after those layers are stable should an SMB consider active-active patterns.
This staged approach keeps spend aligned with business risk and avoids architecture that outpaces the team’s ability to operate it. It also makes partner selection easier. A capable Cloud & DevOps provider should be able to discuss runbooks, traffic management, database replication modes, IAM recovery, deployment pipelines, and test evidence in concrete terms, not just promise “high availability.” That level of specificity is usually the difference between a cloud environment that looks resilient and one that actually is.
Frequently Asked Questions
Does every SMB need a multi-region cloud architecture?
No. Many SMBs are better served by strong backups, infrastructure as code, and a tested warm standby for only their most critical systems. Multi-region architecture is most appropriate when the business impact of downtime justifies the added cost and operational complexity.
What is the difference between high availability and disaster recovery?
High availability reduces service interruption within a normal operating environment, often through redundancy in the same region or across availability zones. Disaster recovery focuses on restoring service after a major failure, such as a regional outage, data corruption event, or destructive misconfiguration.
How often should failover plans be tested?
Critical systems should be reviewed and exercised on a regular schedule, typically at least quarterly or after major architectural changes. The right frequency depends on how often the environment changes and how strict the recovery targets are.
Is active-active always better than active-passive or warm standby?
No. Active-active can reduce recovery time, but it also increases application complexity, data consistency challenges, and operating cost. For many SMB workloads, warm standby or active-passive designs provide a better balance of resilience, simplicity, and budget.
Work with BCW Technology
Planning a project around this? We help small and mid-sized businesses across the USA ship it. Explore our services and portfolio, request a quote, or get in touch.